VeRL-Omni v0.3.0: Async Training and Broader Multimodal Post-Training
VeRL-Omni v0.3.0 expands async RL, makes the V1 trainer the default, and adds reproducible recipes for audio-video generation and multimodal understanding.
Tagged
5 posts
VeRL-Omni v0.3.0 expands async RL, makes the V1 trainer the default, and adds reproducible recipes for audio-video generation and multimodal understanding.
Use RL Insight to locate Trainer and Rollouter bubbles, properly balance training and inference resources, maximize single-card throughput, and enable more efficient training.
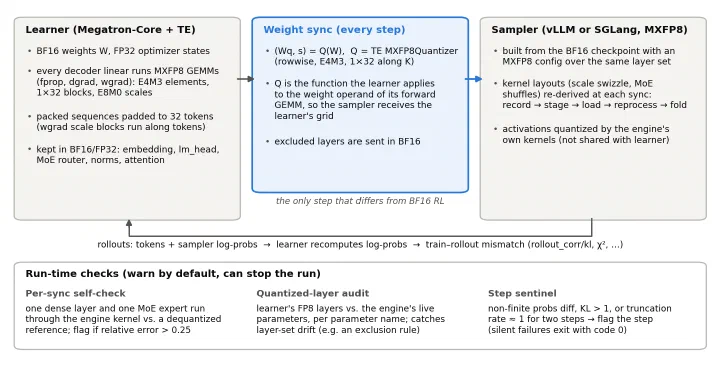
MXFP8 on both sides of RL in verl on B200: a sampler on the learner's weight grid cuts train-rollout KL by 16%, training pays off above about 4.5k tokens per micro-batch, and seven failures show what a sync must preserve.
A release focused on higher-throughput diffusion rollout, reusable omni adapters, and broader recipe coverage.
RL post-training on AMD Instinct GPUs is here: a turnkey ROCm container, AITER-accelerated vLLM and SGLang rollout, and accuracy validated on both MI300 and MI350 series.