VeRL-Omni v0.3.0: Async Training and Broader Multimodal Post-Training
VeRL-Omni v0.3.0 expands async RL, makes the V1 trainer the default, and adds reproducible recipes for audio-video generation and multimodal understanding.
Everything published on this blog, newest first. Posts are written by verl maintainers and contributors; if you have shipped something worth explaining, here is how to write it up .
VeRL-Omni v0.3.0 expands async RL, makes the V1 trainer the default, and adds reproducible recipes for audio-video generation and multimodal understanding.
Use RL Insight to locate Trainer and Rollouter bubbles, properly balance training and inference resources, maximize single-card throughput, and enable more efficient training.
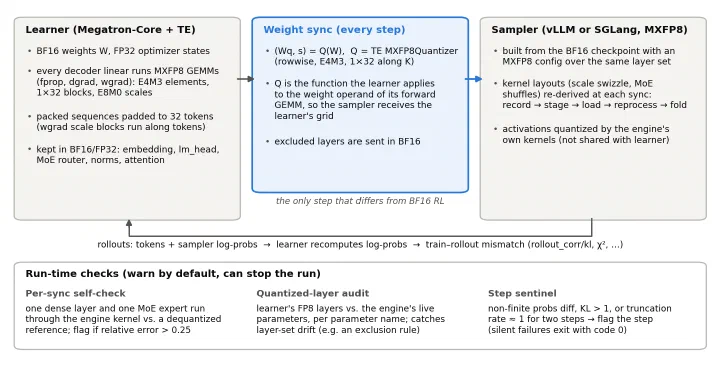
MXFP8 on both sides of RL in verl on B200: a sampler on the learner's weight grid cuts train-rollout KL by 16%, training pays off above about 4.5k tokens per micro-batch, and seven failures show what a sync must preserve.
Uni-Agent is an open framework for scalable long-horizon agent RL. We share our insights on harness adaptation, RL training, and practical recipes for agentic RL.
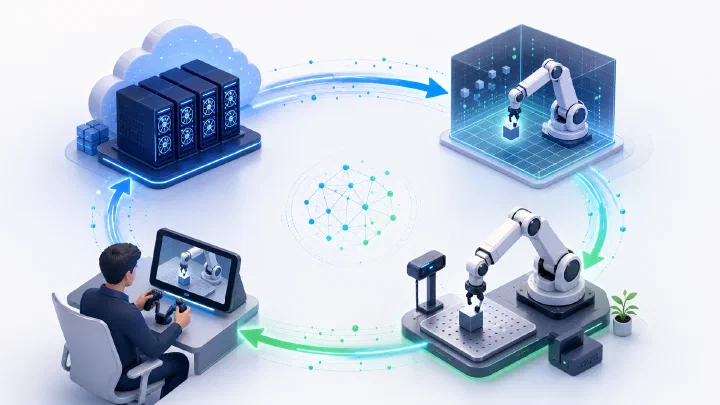
verl-vla is an open-source framework built on verl that unifies human-in-the-loop data collection, fine-tuning, evaluation, and reinforcement learning for vision-language-action policies across cloud and edge resources.
A complete GRPO workflow using verl, Qwen3-30B-A3B, SGLang, and PyTorch FSDP ran for 100 consecutive steps on four AMD Instinct MI455X GPUs, establishing an end-to-end RL baseline for CDNA 5.
A release focused on higher-throughput diffusion rollout, reusable omni adapters, and broader recipe coverage.
RL post-training on AMD Instinct GPUs is here: a turnkey ROCm container, AITER-accelerated vLLM and SGLang rollout, and accuracy validated on both MI300 and MI350 series.
verl-SpeCo 0.1.0 adds native DSpark support and standalone draft model training, with reusable feature storage, seven algorithm backends, vLLM/SGLang integration, and GPU/Ascend NPU support.
Keep the Tinker Cookbook loop you know, and run SFT, RL, and distillation on verl-managed GPU workers you control.