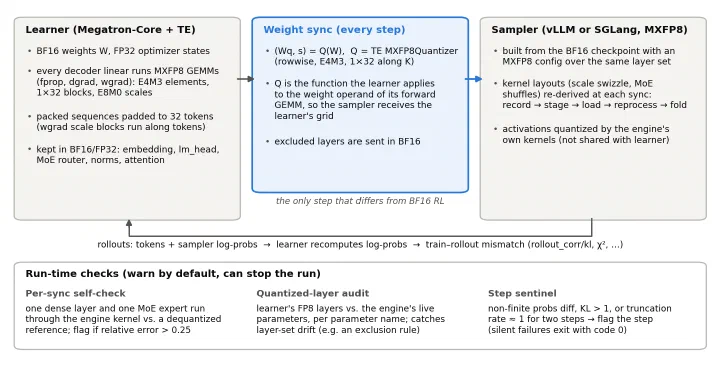
End-to-End MXFP8 RL on Blackwell: What Matching Buys, When It Pays Off, and How It Fails
MXFP8 on both sides of RL in verl on B200: a sampler on the learner's weight grid cuts train-rollout KL by 16%, training pays off above about 4.5k tokens per micro-batch, and seven failures show what a sync must preserve.